JSON hooks
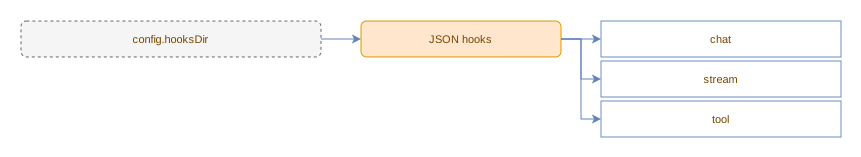
JSON hooks react to LLM events (messages, stream chunks, tool calls)
by writing a JSON file instead of TypeScript. A .json file dropped into a
directory, with the service pointed at it, fires the hook automatically.
How it works
A hook definition has three parts:
target: what to listen to ("chat","stream", or"tool")- Filters: optional fields to narrow when the hook fires (e.g.
roles,regex,chunks) actions: what to do when it fires (log, interrupt, queue a message, …)
A definition may also set label (used in logs and template variables) and
enabled; enabled: false skips registration, and it defaults to true.
When the hook fires, each action in the actions array runs in order. If an
action produces output (like log or queue-message), it can use {{variable}}
templates to insert event data.
Minimal example
Create a file hooks/watch-content.json:
{
    "target": "stream",
    "chunks": ["content"],
    "actions": [
        { "type": "log", "message": "[stream] {{text}}" }
    ]
}
Set the hooks directory and run:
Every content chunk the LLM streams out is now logged to the console:
Targets
chat: react to messages
Fires when a message is added to the chat history. This includes user messages,
assistant responses, tool results: any message except those with
origin: Hook (see queue-message below).
| Filter | Type | Default | Description |
|---|---|---|---|
roles |
string[] |
all roles | Only fire for specific roles ("user", "assistant", "tool", "reasoning") |
regex |
string |
— | Only fire when the message content matches this pattern |
maxTriggers |
number |
unlimited | Stop firing after this many times |
{
    "label": "warn-on-error",
    "target": "chat",
    "roles": ["assistant"],
    "regex": "error|Error|warning",
    "actions": [
        { "type": "warn", "message": "[{{role}}] {{content}}" }
    ]
}
When the assistant says something matching "error" or "warning", the hook logs
it to console.warn. The regex filter targets specific content
patterns; without it the hook fires on every message of those roles.
stream: react to stream chunks
Fires during LLM streaming, once per chunk. Chunks arrive as the model generates tokens, so the hook fires multiple times per response.
| Filter | Type | Default | Description |
|---|---|---|---|
chunks |
string[] |
all chunk types | Filter by chunk type ("content", "reasoning", "tool_call_delta", "usage", "finish") |
{
    "label": "watch-thinking",
    "target": "stream",
    "chunks": ["reasoning"],
    "actions": [
        { "type": "log", "message": "🧠 {{text}}" }
    ]
}
This logs only reasoning chunks (the model's internal chain-of-thought) without printing the final response or tool call metadata.
tool: react to tool execution
Fires when a tool runs. A hook can listen before execution, after execution, or on error.
| Filter | Type | Default | Description |
|---|---|---|---|
tools |
string[] |
all tools | Only fire for specific tool names |
event |
"before" | "after" | "error" |
"after" |
When to fire |
{
    "label": "track-fetch",
    "target": "tool",
    "tools": ["fetch_page"],
    "event": "after",
    "actions": [
        { "type": "log", "message": "fetch_page returned {{result}}" }
    ]
}
{
    "label": "alert-failure",
    "target": "tool",
    "event": "error",
    "actions": [
        { "type": "warn", "message": "Tool {{name}} failed: {{error}}" }
    ]
}
The first logs the result of fetch_page after it runs. The second warns on any
tool error (no tools filter means all tools).
Actions
Actions are the "what happens next" of a hook. Each action is an object in the
actions array. The type field selects the behaviour; extra fields configure
it.
log / warn / info / debug
Print a message to the console at the matching log level.
| Field | Required | Default | Description |
|---|---|---|---|
message |
no | [json-hook] target: {…} |
Template with {{variable}} placeholders |
If message is omitted, a default JSON dump shows the available data while
prototyping.
interrupt
Abort the current LLM request mid-flight. No further chunks are processed; the response is discarded.
Use this to stop generation when unwanted content is detected, for example if the model starts leaking sensitive data:
{
    "label": "stop-on-secret",
    "target": "stream",
    "chunks": ["content"],
    "regex": "api_key|password|secret",
    "actions": [
        { "type": "interrupt" }
    ]
}
interrupt does not use message; it only aborts.
resend: true: auto-retry
Add "resend": true to automatically retry the request after aborting:
{
    "label": "retry-on-error",
    "target": "stream",
    "chunks": ["content"],
    "regex": "error|Error",
    "actions": [
        { "type": "interrupt", "resend": true }
    ]
}
When resend is true, send() loops internally. Each retry sends the same
chat history again and the LLM generates a fresh response. If the new response
also triggers the hook, it retries again; maxTriggers caps this for chat-target
hooks.
queue-message
Queue a synthetic message that is sent on the next LLM request. The message sits
in a queue and is drained when send() runs. Messages queued this way are
tagged with origin: Hook.
Chat hooks with target: "chat" silently skip Hook-origin messages to prevent
infinite loops: a hook that queues a message won't re-trigger itself when that
message is drained into chat history.
| Field | Required | Default | Description |
|---|---|---|---|
role |
no | "assistant" |
One of "user", "assistant", "tool", "reasoning" |
message |
no | [json-hook] target: {…} |
Content of the queued message |
Use case: steer the conversation. When the assistant says "I don't know", queue a user message that pushes it to try again:
{
    "label": "correct-and-retry",
    "target": "chat",
    "roles": ["assistant"],
    "regex": "I don't know|I'm not sure",
    "actions": [
        { "type": "queue-message", "role": "user", "message": "Please try to answer the question." },
        { "type": "interrupt", "resend": true }
    ]
}
The sequence:
1. Assistant says "I don't know"
2. queue-message queues a user message asking it to try again
3. interrupt aborts the current response
4. resend: true triggers a retry; the original messages plus the
queued user message are sent together
5. The model generates a new answer with the extra nudge
When role is "tool", an auto-generated ID is created
(inject-<timestamp>). This allows supplying synthetic tool results.
queue-resend
Set the resend flag without aborting the current request. The send() loop
retries once the current stream finishes. Useful for adding messages to the
queue and triggering a retry without interrupting the ongoing response.
This action has no extra fields; it only sets the flag. Combine it with
queue-message to queue a message and then trigger a retry:
{
    "label": "queue-and-resend",
    "target": "chat",
    "roles": ["assistant"],
    "regex": "I don't know",
    "actions": [
        { "type": "queue-message", "role": "user", "message": "Try again." },
        { "type": "queue-resend" }
    ]
}
The current stream completes normally, the queued message is included on
the next send() loop iteration.
Template variables
The message field in any action supports {{variable}} placeholders. Which
variables are available depends on the target:
| Target | Variables |
|---|---|
| chat | {{label}}, {{target}}, {{role}}, {{content}}, {{match}} (regex capture) |
| stream: content/reasoning | {{label}}, {{target}}, {{type}}, {{text}} |
| stream: tool_call_delta | {{label}}, {{target}}, {{type}}, {{text}}, {{toolCallId}} |
| stream: finish | {{label}}, {{target}}, {{type}}, {{finishReason}} |
| stream: usage | {{label}}, {{target}}, {{type}} |
| tool | {{label}}, {{target}}, {{event}}, {{name}}, {{args}}, {{result}}, {{error}} |
If a variable is missing from the event data it is left as-is in the output
({{missing}} stays {{missing}}).
Combining actions
The actions array runs actions in order. This allows logging, queueing a
message, and interrupting in one shot:
{
    "label": "full-cycle",
    "target": "chat",
    "roles": ["assistant"],
    "regex": "I don't know",
    "actions": [
        { "type": "log", "message": "Triggered retry for: {{content}}" },
        { "type": "queue-message", "role": "user", "message": "Please try again." },
        { "type": "interrupt", "resend": true }
    ]
}
Order matters: queue-message runs before interrupt, so the message is
already queued when the abort-and-retry happens.
Multiple hooks, multiple files
A single file can contain one definition (an object) or several (an array):
[
    {
        "label": "log-stream",
        "target": "stream",
        "actions": [{ "type": "log", "message": "{{text}}" }]
    },
    {
        "label": "log-errors",
        "target": "chat",
        "roles": ["assistant"],
        "regex": "error",
        "actions": [{ "type": "warn", "message": "{{content}}" }]
    }
]
Or split them across files; every .json file in the hooks directory is
loaded independently.
Inspecting registered hooks
Call service.getJsonHooks() to list all loaded hooks:
Each entry has label (always a string, empty if not set in the definition)
and target ("chat", "stream", or "tool"). This is useful for debugging,
displaying active hooks in a UI, or checking that expected hooks are registered.
Configuration
Priority: env var > config value > unset (no hooks loaded).